
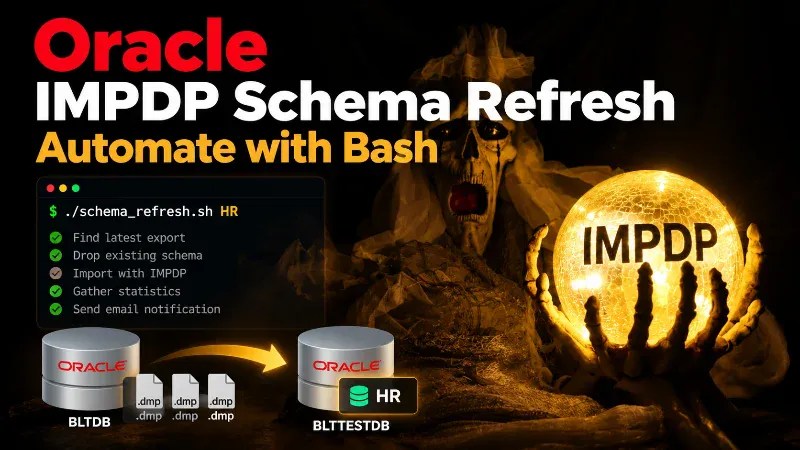
Refreshing schemas in development or test environments with recent production data is a common DBA task. Although Oracle Data Pump makes the import process straightforward, repeatedly identifying dump files, terminating sessions, dropping schemas, importing data, and gathering statistics can become time-consuming.
In my previous article, Oracle Data pump Full Export script with PDB, Retention and Email Notification, I explained how I automate FULL database exports using Bash scripts.
Now it’s time to automate the other side of the process: refreshing a schema in a test database using an existing FULL Data Pump export.
The script I’ll share in this article accepts the schema name as a command-line argument, automatically locates the latest export directory, checks whether the schema already exists, terminates its sessions across Oracle RAC instances, and imports it into the target database.
It also gathers fresh optimizer statistics and sends an email notification indicating whether the operation succeeded or failed.
Of course, there are many additional checks and features that could be implemented, but this approach is sufficient for my requirements. Here is the script. I will explain it, in the later sections.
############################################################################### Oracle Data Pump Schema Refresh# Source Database : BLTDB# Target Database : BLTTESTDB## Usage: ./schema_refresh.sh HR# ./schema_refresh.sh hr# ./schema_refresh.sh Hr############################################################################### Oracle Environmentexport ORACLE_HOME="/u01/app/oracle/product/19.0.0/dbhome_1"export ORACLE_SID="BLTTESTDB1"export PATH="$ORACLE_HOME/bin:$PATH"unset PERL5LIB# ConfigurationSOURCE_DB="BLTDB"TARGET_DB="BLTTESTDB"if [[ -z "${1:-}" ]]; then echo "Usage: $0 <SCHEMA_NAME>" exit 1fi# exact case supplied by the userSCHEMA_NAME="$1"DIRECTORY_NAME="IMPORT_DIR"EXPORT_DIR="/rman/exports/$SOURCE_DB"DUMPFILE="${SOURCE_DB}_%U.dmp"LOGFILE="IMPORT_${SCHEMA_NAME}_$(date +%Y%m%d_%H%M%S).log"MAIL_TO="dba@bulutdb.com"# Find latest export directoryIMPORT_DIR=$(find "$EXPORT_DIR" -mindepth 1 -maxdepth 1 \ -type d -name '20??????_??????' 2>/dev/null | sort | tail -1)ERROR_MESSAGE=""STATUS=1############################################################################### Schema Import Function##############################################################################run_import() { ########################################################################## # Validate Configuration ########################################################################## # Protect administrative schemas regardless of input case case "${SCHEMA_NAME^^}" in (SYS|SYSTEM|PUBLIC|SYSAUX) ERROR_MESSAGE="Refusing to refresh protected schema: $SCHEMA_NAME" return 1 ;; esac # Validate import directory if [[ -z "$IMPORT_DIR" || ! -d "$IMPORT_DIR" ]]; then ERROR_MESSAGE="Import directory not found: $IMPORT_DIR" return 1 fi # Check dump files if ! ls "$IMPORT_DIR"/"${SOURCE_DB}"_*.dmp > /dev/null 2>&1; then ERROR_MESSAGE="No Data Pump dump files found in $IMPORT_DIR" return 1 fi # Check required executables if [[ ! -x "$ORACLE_HOME/bin/impdp" || ! -x "$ORACLE_HOME/bin/sqlplus" ]]; then ERROR_MESSAGE="Oracle executables not found under $ORACLE_HOME" return 1 fi echo "============================================================" echo "Starting Import : $(date)" echo "Source Database : $SOURCE_DB" echo "Target Database : $TARGET_DB" echo "ORACLE_SID : $ORACLE_SID" echo "Schema : $SCHEMA_NAME" echo "Import Dir : $IMPORT_DIR" echo "Dumpfile : $DUMPFILE" echo "Logfile : $LOGFILE" echo "============================================================" ######################################################################### # Create Oracle Directory ######################################################################### if ! sqlplus -S -L "/ as sysdba" <<EOFWHENEVER OSERROR EXIT FAILUREWHENEVER SQLERROR EXIT FAILURECREATE OR REPLACE DIRECTORY $DIRECTORY_NAME AS '$IMPORT_DIR';EXIT;EOF then ERROR_MESSAGE="Oracle directory creation failed: $DIRECTORY_NAME" return 1 fi echo "Oracle directory configured: $DIRECTORY_NAME -> $IMPORT_DIR" ######################################################################### # Check Whether Schema Exists ######################################################################### local SCHEMA_EXISTS if ! SCHEMA_EXISTS=$(sqlplus -S -L "/ as sysdba" <<EOFWHENEVER OSERROR EXIT FAILUREWHENEVER SQLERROR EXIT FAILURESET HEADING OFFSET FEEDBACK OFFSET PAGESIZE 0SET VERIFY OFFSELECT CASE WHEN COUNT(*) > 0 THEN 'YES' ELSE 'NO' ENDFROM dba_usersWHERE username = '$SCHEMA_NAME';EXIT;EOF ); then ERROR_MESSAGE="Failed to check schema existence: $SCHEMA_NAME" return 1 fi read -r SCHEMA_EXISTS <<< "$SCHEMA_EXISTS" echo "Schema exists: $SCHEMA_EXISTS" ######################################################################### # Lock User, Kill Sessions and Drop Schema (If Exists) ######################################################################### if [[ "$SCHEMA_EXISTS" == "YES" ]]; then echo "Schema $SCHEMA_NAME exists. Locking and dropping..." if ! sqlplus -S -L "/ as sysdba" <<EOFWHENEVER OSERROR EXIT FAILUREWHENEVER SQLERROR EXIT FAILURESET SERVEROUTPUT ONSET FEEDBACK ONSET ECHO ONSET VERIFY OFFALTER USER "$SCHEMA_NAME" ACCOUNT LOCK;DECLARE v_sql VARCHAR2(4000);BEGIN FOR r IN ( SELECT inst_id, sid, serial# FROM gv\$session WHERE username = '$SCHEMA_NAME' ) LOOP v_sql := 'ALTER SYSTEM KILL SESSION ''' || r.sid || ',' || r.serial# || ',@' || r.inst_id || ''' IMMEDIATE'; DBMS_OUTPUT.PUT_LINE('KILLING: ' || v_sql); EXECUTE IMMEDIATE v_sql; END LOOP;END;/DECLARE l_cnt NUMBER;BEGIN FOR i IN 1..15 LOOP SELECT COUNT(*) INTO l_cnt FROM gv\$session WHERE username = '$SCHEMA_NAME'; EXIT WHEN l_cnt = 0; DBMS_OUTPUT.PUT_LINE( 'Waiting for ' || l_cnt || ' session(s) to terminate...' ); DBMS_SESSION.SLEEP(2); END LOOP; SELECT COUNT(*) INTO l_cnt FROM gv\$session WHERE username = '$SCHEMA_NAME'; IF l_cnt > 0 THEN RAISE_APPLICATION_ERROR( -20003, 'Cannot drop user. ' || l_cnt || ' session(s) still exist.' ); END IF;END;/DROP USER "$SCHEMA_NAME" CASCADE;EXIT;EOF then ERROR_MESSAGE="Schema drop failed: $SCHEMA_NAME" return 1 fi elif [[ "$SCHEMA_EXISTS" == "NO" ]]; then echo "Schema $SCHEMA_NAME does not exist. Skipping schema drop." else ERROR_MESSAGE="Unexpected schema existence result: $SCHEMA_EXISTS" return 1 fi ######################################################################### # Data Pump Import ######################################################################### echo "Starting Data Pump import: $(date)" impdp 'userid="/ as sysdba"' \ "schemas=\"${SCHEMA_NAME}\"" \ directory="$DIRECTORY_NAME" \ dumpfile="$DUMPFILE" \ logfile="$LOGFILE" \ remap_tablespace=DATA:USERS \ parallel=4 \ cluster=no \ exclude=statistics local IMPORT_STATUS=$? if [[ "$IMPORT_STATUS" -ne 0 ]]; then ERROR_MESSAGE="Data Pump import failed or completed with errors.Exit status: $IMPORT_STATUS" return 1 fi ######################################################################### # Gather Schema Statistics ######################################################################### echo "Gathering statistics for schema: $SCHEMA_NAME" if ! sqlplus -S -L "/ as sysdba" <<EOFWHENEVER OSERROR EXIT FAILUREWHENEVER SQLERROR EXIT FAILUREBEGIN DBMS_STATS.GATHER_SCHEMA_STATS( ownname => '$SCHEMA_NAME', estimate_percent => DBMS_STATS.AUTO_SAMPLE_SIZE, cascade => TRUE, degree => DBMS_STATS.AUTO_DEGREE );END;/EXIT;EOF then ERROR_MESSAGE="Schema import completed, but statistics gathering failed." return 1 fi echo "Schema refresh completed successfully: $(date)" return 0}############################################################################### Execute Import##############################################################################if run_import; then STATUS=0else STATUS=1fi############################################################################### Email Notification##############################################################################if [[ "$STATUS" -eq 0 ]]; then SUBJECT="$TARGET_DB: IMPORT SUCCESSFUL" BODY="$SCHEMA_NAME schema import from $SOURCE_DB to $TARGET_DB and statistics gathering completed successfully."else SUBJECT="$TARGET_DB: IMPORT OPERATION FAILED" BODY="$ERROR_MESSAGE"fiBODY="$BODYSource Database: $SOURCE_DBTarget Database: $TARGET_DBSchema: $SCHEMA_NAMEImport directory: $IMPORT_DIRLog: $IMPORT_DIR/$LOGFILE"if [[ -n "$IMPORT_DIR" && -f "$IMPORT_DIR/$LOGFILE" ]]; then BODY="$BODYLast 20 lines of import log:$(tail -n 20 "$IMPORT_DIR/$LOGFILE")"fiprintf '%s\n' "$BODY" | mail -s "$SUBJECT" "$MAIL_TO"echo "$SUBJECT"exit "$STATUS"
1. Scenario
For this example, I’m using Oracle Database 19c with the following configuration:
| Parameter | Value |
| Source database | BLTDB |
| Target database | BLTTESTDB |
| Target instance | BLTTESTDB1 |
| Export directory | /rman/exports/BLTDB |
| Dump file pattern | BLTDB_%U.dmp |
| Oracle DIRECTORY object | IMPORT_DIR |
| Import parallelism | 4 |
The source database is regularly exported using Oracle Data Pump with FULL=Y. However, I don’t want to import the entire database into my test environment. I only want to refresh a particular schema. Oracle Data Pump supports importing individual schemas from a FULL export by specifying the SCHEMAS parameter.
The overall workflow is:
- Accept the schema name as a command-line argument.
- Locate the latest FULL export directory.
- Validate the required files and Oracle executables.
- Create or update the Oracle DIRECTORY object.
- Check whether the target schema already exists.
- If it exists, lock the account, terminate sessions, and drop the schema.
- Import the requested schema from the FULL export.
- Gather optimizer statistics.
- Send a success or failure email.
The script performs a destructive schema refresh. If the schema already exists, it is dropped using DROP USER … CASCADE before the import. Therefore, it should only be used in a development or test environment.
2. Schema Name as an Argument
Instead of editing the script whenever I want to refresh a different schema, I simply pass the schema name as an argument.
For example:
./schema_refresh.sh HR
The script also accepts:
./schema_refresh.sh hr./schema_refresh.sh Hr
These are not equivalent. Oracle normally stores unquoted usernames in uppercase, whereas quoted identifiers can preserve mixed or lowercase characters. For this reason, the script preserves the exact case supplied by the user.
SCHEMA_NAME="$1"
Before that, it verifies that an argument was provided.
Protecting Administrative Schemas
Because the script drops existing schemas, I also included a basic protection against accidentally refreshing certain internal accounts.
case "${SCHEMA_NAME^^}" in (SYS|SYSTEM|PUBLIC|SYSAUX) ERROR_MESSAGE="Refusing to refresh protected schema: $SCHEMA_NAME" return 1 ;;esac
This is only a basic safeguard, not a complete list of Oracle-maintained or otherwise sensitive schemas.
3. Automatically Finding the Latest Export Directory
My FULL Data Pump exports are stored in timestamped directories.
/rman/exports/
└── BLTDB/
├── 20261022_020000/
│ ├── BLTDB_01.dmp
│ ├── BLTDB_02.dmp
│ └── BLTDB.log
├── 20261023_020000/
│ ├── BLTDB_01.dmp
│ └── BLTDB.log
└── 20261024_020000/
├── BLTDB_01.dmp
├── BLTDB_02.dmp
└── BLTDB.log
Instead of specifying a particular directory manually, I use.
SOURCE_DB="BLTDB"EXPORT_DIR="/rman/exports/$SOURCE_DB"IMPORT_DIR=$(find "$EXPORT_DIR" -mindepth 1 -maxdepth 1 \ -type d -name '20??????_??????' 2>/dev/null | sort | tail -1)
Since the directory names follow the YYYYMMDD_HHMMSS convention, alphabetical sorting also produces chronological ordering. The script then validates that the directory exists.
if [[ -z "$IMPORT_DIR" || ! -d "$IMPORT_DIR" ]]; then ERROR_MESSAGE="Import directory not found: $IMPORT_DIR" return 1fi
Checking the Dump Files
Before proceeding, I check whether the selected directory contains matching dump files.
if ! ls "$IMPORT_DIR"/"${SOURCE_DB}"_*.dmp > /dev/null 2>&1; then ERROR_MESSAGE="No Data Pump dump files found in $IMPORT_DIR" return 1fi
The ls command attempts to match files such as BLTDB_01.dmp and BLTDB_02.dmp. Both standard output and standard error are redirected to /dev/null because I only need the command’s exit status. If no matching file is found, the function returns an error. Note that this verifies the existence of at least one matching dump file, not the completeness or integrity of the export.
4. The Import Function
I organized the refresh operations inside a Bash function. The core logic is as follows :
run_import() {
# Validation
# Oracle DIRECTORY creation
# Schema existence check
# Schema drop
# Data Pump import
# Statistics gathering}
This allows me to keep the main workflow separate from the email notification section.
Whenever a step fails, I set an appropriate error message and return a nonzero status. The function is executed as follows:
if run_import; then STATUS=0else STATUS=1fi
This provides a simple way to determine whether the overall refresh operation succeeded or not.
5. Creating the Oracle DIRECTORY Object
Because the export directory changes with each execution, the script recreates the DIRECTORY object dynamically dependent to IMPORT_DIR.
if ! sqlplus -S -L "/ as sysdba" <<EOFWHENEVER OSERROR EXIT FAILUREWHENEVER SQLERROR EXIT FAILURECREATE OR REPLACE DIRECTORY $DIRECTORY_NAME AS '$IMPORT_DIR';EXIT;EOFthen ERROR_MESSAGE="Oracle directory creation failed: $DIRECTORY_NAME" return 1fi
For example, Bash expands the variables so that Oracle receives.
CREATE OR REPLACE DIRECTORY IMPORT_DIR
AS ‘/rman/exports/BLTDB/20261024_020000’;
Import user must have the required permissions to read the dump files and create the import log in the selected directory. In this example I use sys user.
6. Checking Whether the Schema Already Exists
Before attempting to drop it, I query DBA_USERS. In the script, the schema name is supplied as an input.
local SCHEMA_EXISTSif ! SCHEMA_EXISTS=$(sqlplus -S -L "/ as sysdba" <<EOFWHENEVER OSERROR EXIT FAILUREWHENEVER SQLERROR EXIT FAILURESET HEADING OFFSET FEEDBACK OFFSET PAGESIZE 0SET VERIFY OFFSELECT CASE WHEN COUNT(*) > 0 THEN 'YES' ELSE 'NO' ENDFROM dba_usersWHERE username = '$SCHEMA_NAME';EXIT;EOF); then ERROR_MESSAGE="Failed to check schema existence: $SCHEMA_NAME" return 1fi
The SQL*Plus output is captured in the SCHEMA_EXISTS variable. The expected result is either YES or NO. I then use.
read -r SCHEMA_EXISTS <<< "$SCHEMA_EXISTS"
This reads the first line of the captured output and removes the surrounding whitespace that may have been produced by SQL*Plus formatting.
If the schema exists, the script proceeds with locking, terminating sessions, and dropping the user. If the schema does not exist, these steps (next section ) is skipped. This makes the script useful both for refreshing an existing schema and importing one that is not yet present in the target database.
7. Locking the Schema and Terminating Sessions
If the schema exists, the first step is to lock the account.
ALTER USER "$SCHEMA_NAME" ACCOUNT LOCK;
Locking the account prevents new logins, but it does not terminate existing sessions. Attempting to drop a user while sessions remain connected will result with :
ORA-01940: cannot drop a user that is currently connected
Since, in the sample environment it is running on Oracle RAC, I use GV$SESSION rather than V$SESSION to identify sessions across all instances. You should change it , if yours is single instance.
DECLARE v_sql VARCHAR2(4000);BEGIN FOR r IN ( SELECT inst_id, sid, serial# FROM gv$session WHERE username = 'HR' ) LOOP v_sql := 'ALTER SYSTEM KILL SESSION ''' || r.sid || ',' || r.serial# || ',@' || r.inst_id || ''' IMMEDIATE'; DBMS_OUTPUT.PUT_LINE('KILLING: ' || v_sql); EXECUTE IMMEDIATE v_sql; END LOOP;END;/
Waiting for Sessions to Terminate
Issuing a kill command does not guarantee that the session disappears from GV$SESSION immediately. Therefore, I included a waiting loop.
DECLARE l_cnt NUMBER;BEGIN FOR i IN 1..15 LOOP SELECT COUNT(*) INTO l_cnt FROM gv\$session WHERE username = '$SCHEMA_NAME'; EXIT WHEN l_cnt = 0; DBMS_OUTPUT.PUT_LINE( 'Waiting for ' || l_cnt || ' session(s) to terminate...' ); DBMS_SESSION.SLEEP(2); END LOOP; SELECT COUNT(*) INTO l_cnt FROM gv\$session WHERE username = '$SCHEMA_NAME'; IF l_cnt > 0 THEN RAISE_APPLICATION_ERROR( -20003, 'Cannot drop user. ' || l_cnt || ' session(s) still exist.' ); END IF;END;/DROP USER "$SCHEMA_NAME" CASCADE;
The loop checks up to 15 times, sleeping for two seconds whenever sessions remain. If sessions are still present after the waiting period, the script raises an error instead of continuing. Once no sessions remain, it drops the specied user. The quoted identifier is intentional. It preserves the exact case of the schema name supplied to the script.
8. Importing the Schema from the FULL Export
Once the schema has been dropped, or if it did not exist , the script starts the Data Pump import. Although the source export was generated using FULL=Y, specifying SCHEMAS allows me to import only the requested schema.
impdp 'userid="/ as sysdba"' \ "schemas=\"${SCHEMA_NAME}\"" \ directory="$DIRECTORY_NAME" \ dumpfile="$DUMPFILE" \ logfile="$LOGFILE" \ remap_tablespace=DATA:USERS \ parallel=4 \ cluster=no \ exclude=statistics
There are several parameters worth explaining.
Preserving the Schema Name’s Case
"schemas="${SCHEMA_NAME}""
This passes a quoted schema identifier to Data Pump, allowing the exact case supplied by the user to be preserved. For a normal uppercase schema such as HR, this is equivalent in intent to importing SCHEMAS=HR. For mixed-case or lowercase quoted schemas, preserving the identifier’s case becomes important.
REMAP_TABLESPACE=DATA
The source schema uses the DATA tablespace, but I want its eligible objects imported into the USERS tablespace in the target database. This avoids requiring the same tablespace layout in both environments. The destination tablespace must exist, and the imported user must have the necessary quota or privileges.
PARALLEL=4
The appropriate degree of parallelism depends on the workload, object characteristics, dump-file layout and available resources.
CLUSTER=NO
I explicitly use CLUSTER=NO to keep the Data Pump job on the instance where it was started. This is particularly useful when the dump files are available only through a filesystem mounted on the local instance, or when I simply want to avoid distributing the Data Pump job across RAC instances. I previously encountered a related issue, which I explained in my blog post: ORA-48128: Symbolic Link Error During Data Pump Export.
With CLUSTER=YES, Data Pump can distribute worker processes across RAC instances. In that case, the dump-file directory must be accessible to the instances running those workers. For large jobs, distributing workers across instances may provide performance benefits, but it can also introduce additional coordination overhead. For this schema refresh, I prefer keeping the import on a single instance.
EXCLUDE=STATISTICS
I don’t import optimizer statistics from the production database. Instead, I gather fresh statistics after the import completes.
9. Gathering Optimizer Statistics
After a successful import, the script gathers optimizer statistics for the imported schema.
BEGIN DBMS_STATS.GATHER_SCHEMA_STATS( ownname => '$SCHEMA_NAME', estimate_percent => DBMS_STATS.AUTO_SAMPLE_SIZE, cascade => TRUE, degree => DBMS_STATS.AUTO_DEGREE );END;/
This step runs only after Data Pump completes successfully. If statistics gathering fails, the script records an error and sends a failure notification, even though the import itself may have completed.
10. Error Handling and Email Notifications
The script checks the output of the important operations, including Oracle DIRECTORY creation, schema existence queries, schema dropping, Data Pump import and statistics gathering. For example, after the import:
local IMPORT_STATUS=$?if [[ "$IMPORT_STATUS" -ne 0 ]]; then ERROR_MESSAGE="Data Pump import failed or completed with errors.Exit status: $IMPORT_STATUS" return 1fi
If Data Pump returns a nonzero exit status, the function stops and returns failure.
The main script then sets the final status:
if run_import; then STATUS=0else STATUS=1fi
If run_import returns exit code 1 (anything non-zero), the else block executes, and STATUS is set to 1. I deliberately keep email notification handling outside the function. This avoids repeating the notification code after every possible failure.
Success or Failure Email
The script builds the email subject and body based on the final status.
if [[ "$STATUS" -eq 0 ]]; then SUBJECT="$TARGET_DB: IMPORT SUCCESSFUL" BODY="$SCHEMA_NAME schema import from $SOURCE_DB to $TARGET_DB and statistics gathering completed successfully."else SUBJECT="$TARGET_DB: IMPORT OPERATION FAILED" BODY="$ERROR_MESSAGE"fi
It includes the source database, target database, schema name, import directory, and log-file location. If the Data Pump log exists, the last 20 lines are also included:
if [[ -n "$IMPORT_DIR" && -f "$IMPORT_DIR/$LOGFILE" ]]; then BODY="$BODYLast 20 lines of import log:$(tail -n 20 "$IMPORT_DIR/$LOGFILE")"fi
Finally, the notification is sent using.
printf '%s\n' "$BODY" | mail -s "$SUBJECT" "$MAIL_TO"
The script exits with the refresh status. This allows a scheduler such as cron to distinguish a successful refresh from a failed one.
exit "$STATUS"
11. The Complete Bash Script
The complete script is the schema_refresh.sh version shown above. To execute the script, do not forget to modify ownership and executable grants.
chmod +x schema_refresh.sh./schema_refresh.sh HR
The script automatically performs the refresh steps and sends an email notification when finished.
12. Scheduling with Cron
Once everything is working manually, you can schedule it through cron. Just be aware that, it should be running when the export job is finished. For example, to run the export every day at 03:00.
0 3 * * * ./schema_refresh.sh HR >> /home/oracle/scripts/hrschema_import.log 2>&1
Conclusion
Oracle Data Pump is not only useful for backups and migrations. It is also a practical tool for regularly refreshing development and test environments. By combining an existing FULL Data Pump export with a Bash script, I can refresh a selected schema with using the latest dump files, terminating the current sessions, dropping the old schema and gathering statistics afterward. The script also handles the case where the schema does not already exist and provides a single email notification for both successful and failed operations. There are certainly more sophisticated ways to implement schema refresh automation, but I prefer to keep this solution relatively simple and easy to maintain.
If you’re interested in the export side of this process, you can also read my previous article: Automating Oracle Data Pump Exports.
Hope it helps.


Leave your comment